Contract Repository Migration and Data Quality for Enterprise Legal
Cleaning legacy contracts before migration prevents costly failures in the new system.
A vendor agreement auto-renews for another three years because nobody caught the 90-day notice window buried in a document that lived on a departed employee's laptop. These are not edge cases: they are the normal condition of most enterprise contract portfolios, and the reason most contract repository migrations fail before they ever go live. The failure has little to do with which platform gets selected or how well the project is managed. It has everything to do with what gets carried into the new system: migrating a contract portfolio does not fix the portfolio, it preserves its problems at higher cost, inside a system the organization ends up trusting less than the one it replaced.
Most enterprise organizations find out mid-migration that a meaningful share of their executed contracts is effectively invisible. Ironclad's analysis describes this as the default state, not the exception: legacy contracts scattered across Excel spreadsheets, network drives, personal storage devices, file-sharing software, and generic cloud storage, with each location operating as its own silo, completely cut off from the rest.
Nobody set out to build a fragmented system. Ironclad frames this specifically as a blind spot the organization cannot afford: the team inherits someone else's mess on top of its own, with contracts living in systems it doesn't even have access to anymore.
Carrying that fragmentation straight into a new repository just produces a more expensive replica of the original mess. When classifications are inconsistent, search returns results nobody can rely on, so within months of going live, teams quietly stop using the system and slide back into email and personal folders.
What is stored in a legacy contract portfolio
The formats, locations, and condition in which legacy contracts actually exist make them resistant to anything resembling a straightforward transfer.
Start with format. Many legacy contracts are PDFs of scanned paper documents with no OCR layer applied, so the "text" on the page is actually an image that no system can search. Ironclad notes that legacy contracts are stored in many different formats, PDF, word processor documents, and more, and that this variety alone makes them difficult to manage and edit collaboratively, long before anyone tries to move them anywhere.
The metadata is missing too, on top of the inconsistent formats. Bind's March 2026 evaluation draws the distinction precisely: a shared drive cannot extract the counterparty name, the effective date, the expiration date, or the governing law clause. When metadata has never been captured in the first place, a migration tool has nothing to transfer. That data has to be built from scratch through extraction, not pulled across from an existing field.
Amendments, versions, and related documents compound the problem further, because they are rarely linked to the agreements they modify. LegalEase Solutions notes that disconnected amendments sit alongside duplicate records, missing metadata, and inconsistent classifications as the conditions that can undercut the value of a new repository before it ever opens for business.
Data quality and repository intelligence
A repository populated with clean, structured, complete contract data becomes a source of business intelligence that legal and the rest of the company can query on demand. A repository populated with whatever was sitting in the old system just becomes a costlier version of the old system, with a better login screen.
The line between storage and intelligence runs straight through structured metadata. Contracts stored as unsearchable PDFs with no extracted fields leave the new repository answering the same questions the old shared drive answered: none. Contracts with counterparty, contract type, effective date, expiration date, governing law, key financial terms, and relevant custom fields correctly populated let that same repository answer a question like "which vendor agreements auto-renew in the next 90 days with a termination notice under 30 days" in seconds.
The business functions that depend on clean contract data reach well past the legal department. A repository that legal trusts but that finance, procurement, compliance, and sales cannot use delivers only half the value of one built to serve every one of those functions.
Unclean data produces specific, compounding failures inside the repository itself. When contract type classifications are inconsistent, you cannot trust portfolio-level reporting on exposure or spend, and that unreliability runs straight through to the CFO-readable metrics legal needs to demonstrate its own strategic value.
The cost of letting this go unaddressed is traceable to specific contract failures, not some abstract category of risk. Ironclad points to the joint report from WorldCC and Ironclad, "Closing the Procurement Value Gap," as establishing the financial scale of leakage that flows from unmanaged contract portfolios. Missed renewals, compliance gaps, and lost revenue build up quietly as a business grows, and they stay invisible for exactly the reason the contracts carrying them are invisible.
A legal team that can surface portfolio-level intelligence, renewal exposure, liability concentration, clause frequency across counterparties, is operating as a strategic partner. Making that shift requires a repository the business actually trusts, so you need clean data before and during migration. Cleaning it up afterward, once the problems are buried inside a new system, is a much harder job.
The data quality audit that should happen before any migration begins
A structured audit of the existing contract population should come first in every migration. The goal is not perfection. The goal is knowing what is being moved and in what shape it currently sits.
The second task is assessing the condition of what the inventory found, across four dimensions.
The audit's real output is a migration-ready data map, not a clean dataset. The map specifies which contracts can move as-is, which need metadata extraction, which need duplicate resolution, and which are genuinely missing or beyond recovery. This map governs the cleanup phase, sets a realistic timeline for it, and keeps a team from discovering mid-migration that 40% of the portfolio is in worse shape than anyone expected.
How AI-assisted extraction changes legacy contract cleanup
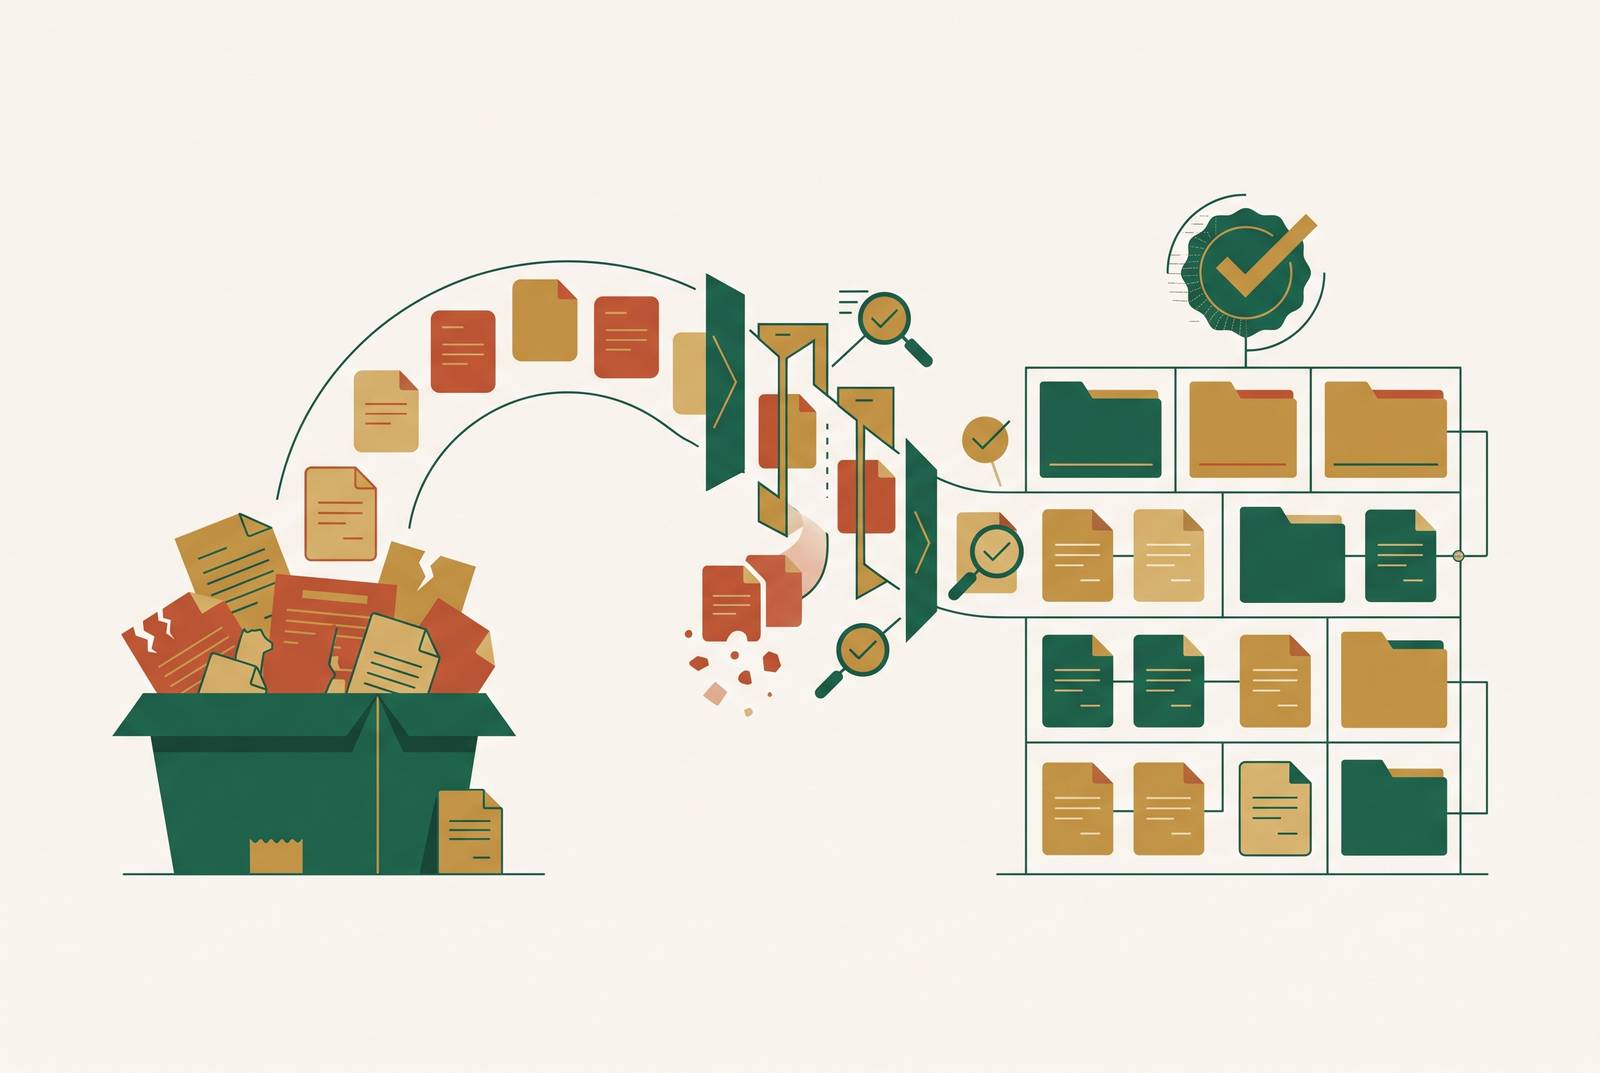
AI-powered metadata extraction makes it economically realistic to clean and structure legacy contract portfolios that would be impossible to remediate by hand, though it still needs a governance layer around it to be trustworthy.
Manual review simply does not scale to enterprise portfolios. A legal team sitting on thousands of legacy contracts in PDF format cannot read, classify, and tag each one by hand before a migration deadline arrives. The economics do not work out. Ironclad frames manual review as the defining limitation of legacy systems: even once an agreement has been found, pulling out something as basic as a renewal date or a party name means reading through the document line by line.
AI extraction automates the parts of the work that are consistent across documents, so review time no longer scales with the number of contracts. Swiftwater & Company describes AI as speeding up legacy contract migration by automatically extracting metadata, classifying document types, and identifying clauses and obligations from unstructured documents, cutting manual review time substantially while keeping data quality consistent across the migrated repository.
AI also surfaces portfolio-level patterns that you would never catch through manual review. When an AI model processes an entire contract population at once, it flags clause frequency shifts, concentration of liability in specific counterparties, or non-standard terms that recur in one business unit's agreements and nowhere else. At that point, migration stops functioning as a storage exercise and becomes an intelligence exercise.
None of this means AI output should be accepted wholesale. Models can misidentify clause types, misread dates in non-standard formats, and sometimes produce field values that simply are not in the document. A structured QA protocol, with defined confidence thresholds and human sign-off requirements, is what separates a trustworthy repository from one that is confidently wrong. Any enterprise AI platform used for this work also needs to meet strict data privacy and security standards: using a customer's contract data to train a model is a line that should not be crossed.
Building the taxonomy and metadata schema that makes the repository queryable
The metadata schema designed before migration decides what questions the repository can answer for years afterward. Teams that treat schema design as a technical detail rather than a strategic decision end up with a system built to answer the wrong questions.
The schema needs to reflect how the business actually uses contracts, not just how legal happens to file them. A schema built purely around legal's document management needs, contract type, counterparty, execution date, cannot support the queries finance and procurement actually need to run. Finance needs payment terms, liability caps, and renewal commitment values. Procurement needs supplier performance obligations and termination conditions. Compliance needs data processing terms and jurisdiction-specific clauses. That conversation should happen across departments before a single field gets defined.
You need deliberate scoping to decide what belongs as a standard field versus a custom field. Every contract record should carry a core set: counterparty name, normalized so "Acme Corp," "Acme Corporation," and "ACME" don't become three separate entries; contract type, drawn from a controlled vocabulary rather than free text; effective date, expiration date, and notice period for termination; an auto-renewal flag and renewal notice deadline; contract value or spend category; governing law and jurisdiction; and document owner and department. Field sprawl gives you a schema that looks thorough on paper but sits practically empty in practice.
Controlled vocabularies and name normalization are not a nice-to-have. A repository where "non-disclosure agreement," "NDA," and "confidentiality agreement" sit as three separate contract types will produce portfolio-level reporting nobody can rely on. Counterparty names need to be normalized against one canonical form for each entity, which is really a small master data management problem sitting inside the larger schema project.
The schema should be treated as a living document, not a one-time migration deliverable. Build in a review cadence from the start, with ownership sitting in legal ops, so schema changes follow business logic.
Running the migration without reintroducing the problems you just cleaned up
The execution phase of a migration carries its own failure modes, separate from data quality, and those failure modes can corrupt a clean dataset if you don't handle the process carefully.
Migrate in prioritized batches. Start with the highest-priority contracts, active agreements, those with renewal dates coming up soon, those carrying the most financial exposure, and validate the output before moving on to the next batch.
Validate the data mapping before any bulk transfer runs. Run a pilot migration on a representative sample and check the output field by field before you commit to the full transfer.
Prevent duplicate creation during the migration itself. Deduplication needs to happen at the source, before migration, not as a cleanup task tacked on afterward.
Keep the old repository running, read-only, through the transition. If a hard cutover happens before that validation, you get a stretch where neither system is trusted, and contracts start scattering back into email and personal drives.
The pressure to go live fast is organizational: business units want the new system now, IT has a project deadline, the vendor has its own implementation timeline. Teams that rush end up with a repository legal trusts and nobody else does, undermining the shift to becoming a strategic partner.
What the repository enables once the data is right
A well-migrated repository with clean, structured data unlocks capabilities that are simply unavailable to teams working off fragmented legacy portfolios, and those capabilities are what move legal from a reactive cost center to a proactive strategic partner.
Alert and monitoring features only work when the metadata behind them is complete. Ironclad frames this as the fundamental promise of the whole exercise: static documents become actionable information that answers questions about obligations, renewal dates, and key terms in seconds.
Portfolio-level intelligence depends on the full population being clean, not just the contracts you executed recently. A team that only migrated its active contracts ends up with a reporting baseline of 12 to 18 months of history, not nearly enough to identify systemic patterns in clause negotiation, liability concentration, or renewal exposure. The historical archive, once cleaned and structured, is what makes it possible to answer a question like how indemnification caps have trended over the last five years, or which counterparty categories tend to push back hardest on standard payment terms. That institutional knowledge currently sits locked inside closed deals and the memories of colleagues who have since moved on, and it is exactly the intelligence that should inform every negotiation going forward.
AI-driven contract review at scale only holds up when the data it references is clean. AI tools that check incoming contracts against a playbook or portfolio standard are only as good as the portfolio behind them. If the historical data is inconsistent or incomplete, the benchmarks the AI is working from are wrong too. A clean repository becomes the foundation for AI-assisted negotiation, risk flagging, and clause benchmarking on every new agreement that comes in, and that compounds the return on the cleanup investment year over year.
When finance can run its own renewal exposure queries, when procurement can pull supplier obligation summaries on demand, when compliance can search by clause type across the entire portfolio, legal has stopped being the bottleneck everyone has to go through and started being the infrastructure the rest of the company builds on. Without clean data, none of that is reachable: not CFO-readable metrics on portfolio risk and outside counsel spend, not proactive risk identification ahead of a renewal or missed obligation, not the negotiation intelligence sitting in years of historical deal data that should shape the next playbook update but currently disappears the moment each deal closes. That is the real measure of a migration done right: legal answering questions before anyone has to ask them.